
AI Search for Your Obsidian Vault - Keyword, Semantic, Hybrid and Agentic Search Explained

This article is part 10 of my series on finding notes in Obsidian. The overview, with the map of all 12 parts, is The Complete Guide to Obsidian Search.
Every tool in the earlier parts of this series relies on words: titles, aliases, tags, phrases. AI search adds meaning. You can ask "that note about feeling stuck" and get your note titled "Procrastination". As you'll see, it works best on top of the note design and structure from part 2 and part 3.
Before installing anything, it helps to know where AI actually earns its place. The first case is when you remember the idea but not the words you used: meaning-based search bridges the gap between "feeling stuck" and "Procrastination". Writing in more than one language is the second, since a multilingual embedding model can match an English question with a French note, which no keyword search can do. Questions that span many notes ("what did I decide about pricing last spring?") are the third: an agent can run several searches, read the hits, refine and summarize, a loop you'd otherwise do by hand. And AI helps you rediscover connections you never wrote down as links.
It's the wrong tool in other cases. If you know the title, the quick switcher answers instantly, while a full hybrid query takes seconds (and more than a minute cold, on my laptop). Know a property or a tag? A Bases filter or [status:Watched] gives you the complete, exact list; semantic search gives you "similar" notes and never tells you what it left out. And for an exact string (a name, an ID, a quote), rg and Obsidian's Search are faster and certain.
So the order from the previous parts of this series doesn't change here: Obsidian's own tools first, AI on top. AI search doesn't replace good titles, aliases, properties and links. It feeds on them. Every piece of evidence below points the same way: the better your structure, the better AI finds your notes, and the easier it is for you to check what it found.
In this article, you'll learn how keyword, semantic and hybrid search differ, how RAG works, why the AI agents I use search with grep rather than embeddings, how to test any search setup with 20 queries, and which risks to manage. The next part covers how to set up and maintain qmd (the local hybrid search engine I use as a bonus layer), which MCP servers let AI assistants search your vault, how my own AI assistant finds things in a vault of about 30,000 notes, and what I think of in-editor AI plugins.
TL;DR
- AI search adds meaning. Ask about "feeling stuck" and get your note titled "Procrastination", or match an English question with a French note. For titles, tags, properties and exact strings, Obsidian's own tools stay faster and certain.
- Hybrid search beats keyword or semantic search alone. Keyword search misses synonyms; semantic search blurs exact identifiers and never comes back empty. In Anthropic's study, combining both and adding a reranker cut retrieval failures by 67%.
- Your headings decide your chunks. Atomic notes often embed as a single chunk. Long notes need descriptive headings, and templates add noise to the index.
- The terminal agents I use search with grep, not embeddings. Claude Code, Codex, Gemini CLI and opencode are lexical by default, so put the words you'll search with in your files: titles, aliases, summaries.
- Test any setup with 20 real queries and score it with Recall@5 and MRR.
qmd benchautomates it. - Manage the risks: embeddings can be inverted, stale indexes hide notes without telling you, citations can be wrong, and AI-written notes compete with yours in the results.
Keyword, semantic and hybrid search
Two words from information retrieval help here. Recall is the share of all relevant notes that a search returns. Precision is the share of returned notes that are actually relevant. "Did I ever write anything about X?" needs recall. "Open my note on X" needs precision.
- Keyword search (Obsidian Search, Omnisearch,
rg, and the BM25 ranking algorithm behind many search engines) matches the literal words. It's excellent for names, IDs, acronyms, rare terms and exact phrases. It misses synonyms and paraphrases: "car" won't match "automobile", "burnout" won't match "exhaustion", and an English query won't find a French note. - Semantic search turns text into embeddings (lists of numbers that capture meaning) and finds notes whose meaning is close to your query. It catches paraphrases and vague memories. But it blurs exact identifiers. Anthropic's example: a semantic search for "Error code TS-999" may return general content about error codes and miss the one note with that exact string.
- Hybrid search runs both and merges the results.
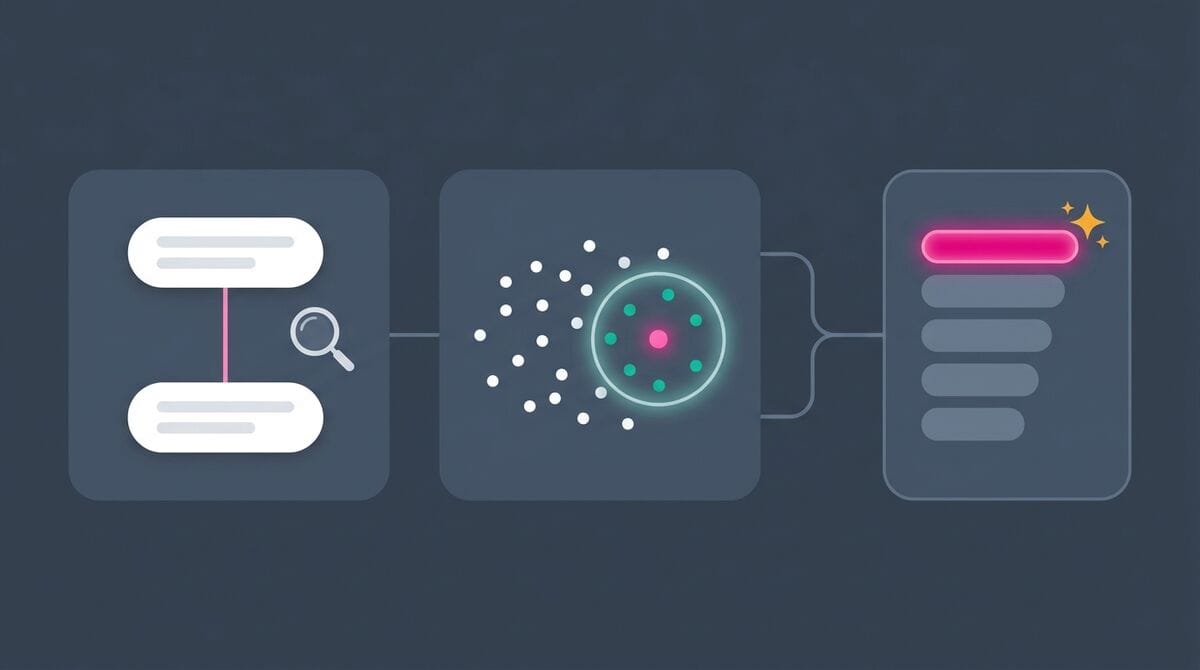
The evidence favors hybrid search. The BEIR benchmark (2021) found that "BM25 is a robust baseline" and that dense (semantic) retrievers often underperform outside the domain they were trained on. Anthropic's "Contextual Retrieval" study (2024) measured how often the right chunk was missing from the top 20 results:
| Setup | Retrieval failures |
|---|---|
| Contextual embeddings alone | 35% fewer failures (5.7% → 3.7%) |
| Contextual embeddings + contextual BM25 | 49% fewer (2.9%) |
| Both + reranking | 67% fewer (about 1.9%) |
The "contextual" part matters for us: they prepend a short description of the whole document to each chunk before indexing it. Context and metadata make AI retrieval better. In a vault, that context is your titles, note types and properties.
Here's how that plays out with real queries:
| What you search for | Keyword search | Semantic search | Best choice |
|---|---|---|---|
A name, an ID, an acronym (TS-999, PKM) | Finds the exact notes | May return notes "about" the topic and miss the exact one | Keyword |
An exact phrase ("progressive summarization") | Finds every note that contains it | Finds them too, plus notes on related ideas | Keyword for precision, semantic for recall |
| A paraphrase ("how to find old notes quickly") | Only works if those words are in the note | Found my Ways to locate notes note | Semantic |
| An English question about a French note | Misses | Finds it with a multilingual model | Semantic |
A property value ([status:Watched]) | Exact and complete in Obsidian Search or Bases | Not designed for it | Obsidian |
One gotcha: semantic search never comes back empty. Every query has nearest neighbors, so you always get results, even when nothing relevant exists in your vault. Keyword search tells you "no match"; semantic search shows you its best guess with a score. Scores are only meaningful relative to the same tool and model. My qmd skill treats scores above 0.8 as strong matches, 0.5 to 0.8 as moderate, and below 0.2 as noise. Learn what "nothing relevant" looks like in your tool before you trust its "something".
You can get hybrid search today in three ways: a tool that does both in one query (qmd's query command, covered in part 11), two tools side by side (Omnisearch for words, a semantic plugin for meaning), or an AI agent that has both a keyword tool and a semantic tool and picks per question. I use the first and the third.
RAG in two minutes
Retrieval-Augmented Generation (RAG) is how most "chat with your notes" tools work: find the relevant notes first, then give them to a language model to answer. The pipeline looks like this:
- Parse your notes (strip or keep the frontmatter, resolve links)
- Chunk them into passages (qmd uses about 900 tokens with 15% overlap; atomic notes are often one chunk each, which is a nice advantage)
- Embed each chunk with an embedding model
- Index the chunks for keyword search (BM25) and vector search
- Retrieve candidates with both
- Fuse the two result lists (usually with Reciprocal Rank Fusion)
- Rerank the top candidates with a model that reads query and passage together
- Generate an answer that cites the source notes
Two techniques you'll see mentioned: query expansion (a model rewrites your query into several keyword and semantic variants) and HyDE (the model writes a hypothetical answer, and you search with that instead of your short question).
Three of these steps decide most of the quality you'll get from your own notes: chunking, reranking and the query itself.
Chunking: let your headings do the work
A chunk is the unit that gets embedded and returned. If a chunk mixes three topics, its vector is a blur of all three, and it matches none of them well.
qmd's chunker is a good model of what works for Markdown. It aims for about 900 tokens, but instead of cutting at a fixed position it looks back up to 200 tokens for the best break point. Headings score highest (100 for an H1, 90 for an H2, 80 for an H3), then code block boundaries (80), horizontal rules (60), blank lines (20) and list items (5). A heading 200 tokens back still beats a plain line break at the target position. Code blocks stay whole. And before embedding, qmd puts the note's title in front of each chunk ("title | text"), a cheap version of Anthropic's contextual chunks: every passage carries the name of the note it came from.
What that means for how you write:
- Atomic notes are ideal. One idea, one note, often one chunk. The vector represents exactly that idea.
- Long notes need descriptive headings. Daily notes, meeting logs and project notes get split at headings. A heading like "Notes" tells the model nothing; "Pricing decision for the course" puts the topic right where the chunk starts.
- Templates and boilerplate add noise. Template folders, Dataview and Templater code, and the identical scaffolding of daily notes create near-duplicate chunks that crowd out real content. Exclude template folders from the index (shown in the qmd section of part 11).
- Decide what to do with frontmatter. My recommendation: tags and aliases are worth keeping in the embedded text, since they describe the note; long lists of IDs and dates mostly add noise.
Fancy chunkers matter less than you'd think. Chroma's 2024 evaluation found that a plain recursive splitter with chunks of about 200 tokens reached about 88.5% recall, while an LLM-based semantic chunker reached 91.7% recall but lower precision. Chunk size and overlap mattered more than the method.
Reranking: the biggest gain for the least effort
An embedding model encodes your query and each passage separately, then compares the vectors. A reranker reads the query and a passage together and judges how well that passage answers that query. That's far more accurate, and far slower, so it only runs on the top candidates of the first pass.
In Anthropic's numbers above, reranking took the failure reduction from 49% to 67%. qmd uses a 0.6B-parameter Qwen3 reranker on the top 40 candidates by default (change it with -C), and then blends its score with the original retrieval rank: 75/25 in favor of retrieval for the top 3 results, 60/40 for ranks 4 to 10, and 40/60 for the rest. The qmd docs explain that this "prevents the reranker from destroying high-confidence retrieval results". The cost is time: on my laptop, a warm hybrid query takes 10 to 16 seconds with reranking and 9.7 to 12.7 seconds without (--no-rerank).
Query expansion and HyDE, by example
Short questions make poor search vectors. "How do I make notes easier to find?" is eight words; the notes that answer it are hundreds of words long and use different vocabulary.
HyDE (Hypothetical Document Embeddings, Gao et al., 2022) fixes that by having a model write a fake answer first, for example: "To make notes easier to find later, give them explicit titles, add aliases for the other names you might use, link them from a Map of Content, and summarize the key idea in the first lines." Then it searches with the vector of that paragraph. A fake answer looks a lot more like your real notes than the question does, so it lands closer to them.
Query expansion does the same job for both halves of hybrid search. qmd ships a small fine-tuned model (1.7B parameters) that turns your question into typed sub-queries: lex lines for BM25, vec lines for vector search, and hyde lines with a hypothetical answer. You can also write those lines yourself, which is faster and often better when you know what you're looking for (examples in the qmd section of part 11).
The results of all those sub-queries are merged with Reciprocal Rank Fusion. Each result list gives a note a score of 1/(k + rank), with k = 60 by convention, and the scores are summed. A note that ranks well in several lists floats to the top, without having to compare BM25 scores with vector distances. qmd adds a bonus for top-ranked results, because, in its docs' words, "Pure RRF can dilute exact matches when expanded queries don't match".
Choosing an embedding model
If you run things locally, the embedding model matters. A few popular open models, with their mean score on the MTEB multilingual benchmark (from the model cards):
| Model | Size | Context | MTEB multilingual (mean) |
|---|---|---|---|
| EmbeddingGemma 300M | 308M parameters | 2,048 tokens | 61.15 |
| Qwen3-Embedding-0.6B | 0.6B | 32K | 64.33 |
| Qwen3-Embedding-8B | 8B | 32K | 70.58 |
| BGE-M3 | about 568M | 8,192 | 59.56 |
Leaderboard scores average many task types, so test on your own notes. Two gotchas: some models need specific prefixes on queries and documents (forget them and quality drops silently), and changing the model means re-embedding everything.
How to read that table for a vault:
- Languages. All four are multilingual (100+ languages). If you write in two languages, that's the first requirement, and English-centric models (like the older nomic-embed-text v1.5, a common default in Ollama-based plugins) are a poor fit.
- Size and speed. EmbeddingGemma runs comfortably on a laptop, which is why qmd uses it by default. Qwen3-Embedding-8B scores best but needs serious hardware to embed tens of thousands of notes. Qwen3-Embedding-0.6B is the middle ground, and qmd documents it as an alternative.
- Context length. With chunks of about 900 tokens, a 2,048-token limit is enough. It matters if a tool embeds whole notes instead of chunks.
- Prefixes. EmbeddingGemma expects queries formatted as
task: search result | query: ...and documents astitle: none | text: ...; nomic-embed-text v2 requiressearch_query:andsearch_document:. qmd and the mainstream plugins handle this for you. If you build your own pipeline, read the model card first. - Dimensions. EmbeddingGemma supports Matryoshka truncation (768 dimensions down to 512, 256 or 128), which makes the index smaller at a small cost in quality.
To switch models in qmd, set models.embed in ~/.config/qmd/index.yml (or the QMD_EMBED_MODEL environment variable) to the model's GGUF address, then run qmd embed -f to re-embed everything. Vectors from different models are not comparable, so there's no partial migration.
Don't dump your whole vault into the context
One thing RAG is NOT: dumping your whole vault into a model's context window. The "Lost in the Middle" study (Liu et al., 2023) showed that models use information at the start and end of a long context much better than information in the middle, and that adding more documents can make answers worse. Newer models have reduced this effect, but not removed it. Precise retrieval still matters.
In the study, GPT-3.5 given 20 to 30 documents sometimes did worse than with no documents at all. For your notes, the practical rule is the same one I give my AI assistant: find a short list of candidates, read snippets, then open only the 3 to 5 notes that matter.
Agentic search vs RAG
There's a third approach, and it's the one I use most: let an AI agent search the files itself, with the same tools you'd use.
Boris Cherny, who leads Claude Code, wrote on Hacker News in February 2025: "Claude Code doesn't use RAG currently. In our testing we found that agentic search out-performed RAG for the kinds of things people use Code for." The reasons he gave later: there's no index to keep in sync, results are always fresh, and it's simpler and safer. The cost is latency and tokens. The agent searches, reads, refines its query and follows references, much like the participants of Jaime Teevan's 2004 study, who re-found their information by orienteering: small steps from something they knew (see the overview of this series).
How the main terminal agents search by default:
| Agent | Default search tools |
|---|---|
| Claude Code | Grep (ripgrep), Glob, Read |
| Codex CLI | rg and rg --files (its system prompt says to prefer them) |
| Gemini CLI | glob, grep_search, read_file |
| opencode | grep and glob, built on ripgrep |
All of them are lexical by default. So your vault is "agent-findable" to the extent that the words you'll ask with literally appear in your files: titles, aliases, tags, summaries. That's another reason for the acronym trick from part 2. And since ripgrep skips .gitignored and hidden folders, notes in those folders are invisible to the agent.
Other measurements nuance this. Cursor measured a 12.5% average accuracy gain when its agent had semantic search in addition to grep, and concluded that the combination works best. A 2026 paper titled "Is Grep All You Need?" found that grep generally beat vector retrieval on a long-conversation memory benchmark, and that the scores depended strongly on the agent harness (how the agent calls its tools and reads their results). And the Augment team, after finding that grep was enough on SWE-Bench, noted that embeddings still matter for unstructured content such as chat messages and documentation, and advised exposing existing retrieval systems as tools for agents rather than throwing them away.
Code is full of unique identifiers, which grep finds easily. Notes are prose, full of synonyms. So my take for a vault: give the agent rg, the Obsidian CLI (for links, backlinks and properties) and a hybrid index exposed as a tool (qmd), and let it choose.
Make your vault agent-findable
Since agents search with words first, the work is the same as for humans, with a few agent-specific details:
- Put the words in the files. Explicit titles, aliases, a one-line summary or
descriptionproperty at the top of important notes. If you'd ask "notes about burnout", make sure "burnout" appears in the notes about exhaustion (an alias does it). - Check your ignore files. ripgrep-based agents skip whatever
.gitignoreexcludes, plus hidden folders. If a folder of notes is git-ignored on purpose, a.ignorefile containing!that-folder/makes ripgrep see it again (opencode documents this). The other way around, a.ignorefile is a cheap way to hide attachments, templates and archives from agents. - List, then snippet, then read. Ask for file lists before content:
rg -l -i "term" .(matching files),rg -c -i "term" .(match counts per file),qmd query --files "question"(ranked paths only). Then read the 3 to 5 notes that matter. This saves tokens and keeps the relevant notes out of the "middle" of a huge context. - Search every language you write in. Keyword tools are language-literal: a search for "writing" won't find a note about "écriture". Tell the agent which languages you write in, and to search with the words of each.
- Tell it which tool answers which question. Exact names and IDs:
rgorobsidian search. Concepts: qmd. Links, backlinks, tags and properties: the Obsidian CLI, which understands aliases and wikilinks (ripgrep doesn't). I share my exact rules in the snippet further down.
A prompt that applies all of this, which you can reuse as is: "Find my notes about X. Search titles and aliases first, then content. List the matching files before reading any of them, read at most five, and cite the path of every note you use. If you find nothing, say so."
Andrej Karpathy's "LLM wiki" pattern makes the same point from another angle. The LLM reads an index.md catalog first (one line per page, with a one-line summary), then drills into the pages it needs. That works up to a few hundred pages without any embeddings. At larger scale, he names qmd as the search tool. Findability work moves from query time to write time: summaries, an index and cross-links. Maps of Content do the same job.
In Obsidian terms, that index.md is a Map of Content, ideally one that maintains itself with a serialized query (see part 8), because an agent reads the Markdown file, not what Dataview renders on screen. My LLM Wiki note covers the pattern in more detail.
Use AI to retrofit findability into old notes
AI is also good at fixing a messy vault. The work that makes notes findable (a better title, an alias, a one-line description, a type, a few links, a place in a MoC) is exactly the kind of tedious, repetitive work you never get around to on 3,000 old notes. An agent can propose it in bulk. You decide what goes in.
The workflow I recommend:
- Commit first. Make sure your vault is under git (or backed up) before any agent touches it. Every change should be one
git diffaway from being reviewed or undone. - Work in small batches. One folder, one note type, or the 50 notes that failed your search tests. Not the whole vault at once.
- Ask for proposals, not edits. Have the agent produce a review table: note, proposed alias, proposed description, proposed type or tags, proposed links. Accept or reject each row, then let it apply only what you approved.
- Re-run your 20 queries (next section). If the scores didn't move, the changes didn't help.
My Obsidian Starter Kit ships AI skills that follow this "propose, then apply on approval" pattern:
osk-vault-alias-generatorfinds notes that should have aliases (acronyms, alternate names, translations, common misspellings) and presents suggestions before adding anything.osk-vault-orphan-rescuefinds notes with no incoming and no outgoing links, and suggests where each one belongs in your graph.osk-vault-link --mode suggestproposes links for a given note; its other modes measure link density or turn plain mentions into links.osk-vault-moc-gapsfinds topic clusters of 10 or more notes without a Map of Content, and MoCs that are out of date.osk-vault-tag-harmonizemerges duplicate tags and fills in missing type tags, andosk-vault-fix-notesbackfills missing required properties (additive only, dry run first).
If you'd rather stay inside Obsidian, the AI Tagger plugin tags the current note with one click. It requires an OpenAI API key, and it hasn't been updated since 2024.
Gotchas: AI-suggested aliases can be too generic ("Notes", "Ideas") and then create noise in every search; reject those. Descriptions written by a model describe what the note says, not why you kept it; edit the ones that matter. And keep the provenance visible: notes written entirely by AI deserve a marker (an ai_generated property or their own folder, as described in "AI-written notes polluting your results"), and for small edits, the git history is your record. For a broader checklist of what makes a vault usable by AI, see PKM-to-AI Readiness.
Test your search with 20 queries
Before you trust any search setup (or switch tools), test it. Your impression of a search tool is a poor guide: you remember the one time it found a forgotten note, and you forget the ten times you gave up and browsed instead. This simple method is adapted from standard information retrieval practice, and it takes about an hour the first time and a few minutes after that.
- Write down 20 real queries you've had, with the note(s) you expected to find. Mix them: 5 exact (names, IDs, titles), 5 paraphrases ("that note about feeling stuck"), 5 vague or multi-step ("what did I decide about pricing last spring"), 3 in another language, and 2 whose answer isn't in your vault.
- Run each query through each tool you want to compare: Obsidian Search, Omnisearch,
rg, qmd keyword search, qmd hybrid query. - For each, note whether the expected note appears in the top 5, and at which rank. For the two negatives, check whether the tool returns confident junk.
- Keep the list in a note. Re-run it when you change tools, models or settings.
You'll often find that the fix is on the content side: an alias, a better title, or a one-line summary at the top of the note.
Here's how to do each of those steps well, plus a way to automate the test.
Build the query set
"Real" is the important word. Don't invent queries that you know will work. Collect the ones you actually had: things you searched for this month, "I know I wrote about this somewhere" moments, questions you asked an AI assistant about your notes. Then write down the note you expected to find, by its exact name, before running any search. Otherwise you'll accept whatever comes up first as "the right answer".
Map the mix to the "What do you remember?" table in the overview of this series, so the test covers the way you actually search. Here's what a few rows could look like on my vault (the expected notes are real):
| # | You remember… | Query | Expected note |
|---|---|---|---|
| 1 | The title | Zettelkasten | Zettelkasten (MoC) |
| 2 | An acronym | AI | Artificial Intelligence (AI) |
| 3 | An exact phrase | "progressive summarization" | Progressive summarization |
| 4 | Only the idea | how to find old notes quickly | Ways to locate notes |
| 5 | Only the idea | how to make notes easier to find again later | Progressive summarization, and "Each tag and link you add to a note adds a path to resurface that note later on" |
| 6 | When and what, roughly | what did I decide about ARD mode last month | The session summary of September 23 |
| 7 | The idea, in another language | comment retrouver rapidement mes anciennes notes | Ways to locate notes |
| 8 | Nothing (negative) | a topic you know you never wrote about | No note |
Include a couple of queries for notes that are hard to reach: notes in deep folders, notes with odd titles, recent notes (to catch stale indexes), notes inside folders you excluded somewhere.
Run every query through every tool
Use the same intent for every tool, but phrase it the way you'd naturally phrase it for that tool: keywords for keyword tools, a sentence for semantic ones.
# Obsidian's own index (scope it in big vaults)
obsidian search query="progressive summarization" limit=5

# ripgrep: unranked, so note whether the note is in the list, and how long the list is
rg -il --glob '*.md' "progressive summarization" ~/vault | wc -l

# qmd: keyword only, semantic only, then the full hybrid pipeline
qmd search "progressive summarization" -n 5
qmd vsearch "how to make notes easier to find again later" -n 5
qmd query "how to make notes easier to find again later" -n 5
Run Omnisearch and any in-editor plugin by hand from their search box. Note the time each tool takes too. A tool that finds 10% more but takes 20 times longer may be right for "where did I write about X?" and wrong for everyday lookups.
Score it
Keep a table in a note with one row per query and one column per tool, and write the rank of the first expected note in each cell (or "none" if it's not in the top 5). Then compute two numbers per tool, over the 18 queries that have an answer:
- Recall@5: the share of queries where an expected note appears in the top 5. This answers "will I find it at all on the first screen?"
- MRR (Mean Reciprocal Rank): for each query, 1 divided by the rank of the first expected note (rank 1 = 1, rank 2 = 0.5, rank 5 = 0.2, not found = 0), then the average. This rewards tools that put the right note first, which is what search feels like when it works.
A quick example with four queries: a tool finds the expected notes at ranks 1, 3 and 2, and misses one. Recall@5 is 3/4 = 0.75. MRR is (1 + 0.33 + 0 + 0.5) / 4 ≈ 0.46. Research benchmarks like BEIR and MTEB use a more refined metric (nDCG@10), but for personal use, Recall@5 and MRR tell you everything you need.
Score the two negative queries separately. Did the tool say "nothing found", or did it show five results that looked convincing? Semantic tools will always show something, so look at the scores: if junk scores as high as real hits, you can't trust that tool's "something" either.
Automate it with qmd bench
If you use qmd, it has a benchmark command built in. Write your query set as a JSON fixture:
{
  "description": "My vault search test",
  "version": 1,
  "collection": "notes",
  "queries": [
    {
      "id": "locate-notes",
      "query": "how to find old notes quickly",
      "type": "semantic",
      "expected_files": ["Permanent notes/Ways to locate notes.md"],
      "expected_in_top_k": 5
    }
  ]
}
Then run qmd bench my-fixture.json -c notes. It runs every query against four backends (keyword only, vector only, hybrid without reranking, and the full pipeline) and reports precision@k, recall, MRR and F1 for each. The type field (exact, semantic, topical, cross-domain, alias) only labels queries for grouping, which maps nicely onto the categories above. The expected_files paths must match what qmd ls prints.
Two gotchas. If the collection isn't indexed, qmd bench runs to completion and reports all zeros without any warning, so check qmd ls notes first. And if half your notes have no embeddings yet, the vector backend can't find them: run qmd status first, or you'll be measuring how stale your index is, not how good semantic search is.
Fix what failed
Every miss tells you something. The usual causes and fixes:
| What happened | Likely cause | Fix |
|---|---|---|
| An exact query misses the note | The word isn't in the title or the note; or the note is in an excluded or ignored folder | Rename the note or add an alias; check Obsidian's Excluded files, .gitignore, qmd's ignore patterns |
| An acronym query misses | The note only uses the full term | Put the acronym in the title in parentheses (part 2) |
| Paraphrases fail in keyword tools | Expected: keyword tools match words | Add an alias or a one-line summary with the words you'd use, or use a semantic tool for this kind of query |
| Paraphrases fail in the semantic tool | The note has no embeddings yet, or it's long and covers many topics | Run qmd status and qmd embed; split the note or give its sections descriptive headings |
| The right note shows up at rank 8 | Noise above it: templates, archives, duplicates, AI-generated notes | Exclude those folders from the index, add contexts, scope your searches |
| Queries in your other language fail | English-only model, or keyword search | Use a multilingual model; add aliases in both languages to key notes |
| Negatives return confident junk | Semantic tools always return neighbors | Use a minimum score (qmd query --min-score 0.4) and treat low scores as "not found" |
| Multi-step questions fail everywhere | No single search can answer them | Use an agent that searches in a loop, and keep decisions in notes with a fixed "Decisions" heading |
Then re-run the test after you change tools, embedding models, chunking or ignore rules, and after any big reorganization of your vault. The note with your 20 queries becomes a small regression test for your second brain.
Keep a search log
The 20-query test is a snapshot. Your real searches happen every day, and the failed ones are the most valuable data you have about your vault: each one tells you exactly which note is hard to find, and with which words you looked for it. Obsidian's Search view remembers your last 20 queries (on each device), but not whether they worked. The quick switcher only remembers the notes you opened, not what you typed.
So keep a log. A single note works, or a line in your daily note. Each time a search fails or takes too long, write one line:
| Date | What I typed | Where | What I was looking for | What finally found it | Fix |
|---|---|---|---|---|---|
| 2026-10-02 | pricing call | Quick switcher | Meeting notes about ACME pricing | Browsing the daily note of that week | Renamed to 2026-09-24 Pricing call with ACME |
| 2026-10-05 | burnout | Search | My note on exhaustion | A backlink from a book note | Added the alias "burnout" |
Each line takes a few seconds to write. If you live in the terminal, obsidian append path="Search log.md" content="..." adds a line without switching windows.
Once a month, go through the log and fix what's still open. Then look at the Fix column: it tells you which layer of the findability stack (part 1) keeps failing. Mostly renames? Your naming habits need work at capture time. Mostly aliases? You think of things with other words than the ones you write. Mostly "found it through a link"? Your links work, but your titles don't.
Two more uses for the log:
- Feed the test set. Move the best misses into your 20 queries. Your regression test then grows with the searches you actually failed, instead of the ones you imagined.
- Count the misses. The number of new lines per month is a rough but honest findability metric. If it goes down while your vault grows, your system is working.
This is the habit version of "Rename after a failed search" (part 2): instead of fixing one note on the spot, you collect the evidence and fix the patterns.
Risks of AI search
Each risk below comes with the mitigation I use or recommend.
- Privacy. Cloud models and cloud embedding APIs see your notes. And embeddings are not anonymous: the Vec2Text study (Morris et al., 2023) recovered short texts almost perfectly from their embeddings. Treat a vector index (
.smart-env/,~/.cache/qmd/index.sqlite) as sensitively as the vault itself: keep it out of public repositories and out of your sync if you can. More in my practical guide to AI privacy. - Stale indexes. Anything you changed after the last embedding run is invisible to semantic search.
- Hallucinated or misattributed citations. Always open the source note.
- AI-written notes you never read. If agents write into your vault, they compete with your own notes in search results, and you can't recognize them as "yours". Keep them in their own folders and scope your searches.
- Cognitive debt. If AI does all the finding, you may stop knowing what you know. A 2025 MIT Media Lab preprint ("Your Brain on ChatGPT", 54 students, still debated) found the weakest brain engagement in the group using an LLM. Earlier, Sparrow and colleagues (2011) found that when people expect to access information later, they remember where it is better than the information itself (another experiment from the same paper failed to replicate in 2018, but this one wasn't part of that test).
My counter-strategy: use AI to surface notes. Then read them, link them and decide yourself.
The sections below go through each risk and what to do about it.
Privacy and embedding inversion
The Vec2Text result is stronger than it sounds: the researchers recovered 32-token inputs almost perfectly from their embeddings, and pulled full names out of embedded clinical notes. Later attacks go further: one (2024) infers sensitive details through a stand-in model, without any access to the original embedding model. So "I only send embeddings, not my notes" doesn't protect anything.
What to do: for a private vault, prefer local embedding models (qmd, Smart Connections and Similarity all run locally by default). Know where each index lives: qmd's is outside your vault, in ~/.cache/qmd/, while Smart Connections stores .smart-env/ inside it, so add that folder to your sync tool's ignore list and to .gitignore. Encrypt your backups. And before connecting a cloud assistant to your vault through MCP, decide which folders it may read; a journal and a customer folder deserve stricter rules than your permanent notes.
Stale indexes
This is the risk I actually hit: a third of my vault was invisible to semantic search, and nothing told me unless I asked. It's also the main reason Claude Code's team chose agentic search over RAG.
What to do: schedule qmd update and qmd embed (see the checklist in part 11), check qmd status before trusting a "nothing found", and tell your agent to do the same and to warn you when embeddings are pending. Keep rg in the loop: it reads the files on disk, so it's never stale.
Lost in the middle
Giving a model more notes doesn't mean better answers. Relevant information in the middle of a long context gets used less, and in the original study, too many documents made some answers worse than none.
What to do: retrieve a few good notes rather than many vague ones. List, then read snippets, then open 3 to 5 notes. Put your strongest signal first in typed queries. And prefer atomic notes, which give the model one focused passage instead of a long note with the answer buried in paragraph twelve.
Hallucinated or misattributed citations
A model can cite a note that doesn't exist, attach a quote to the wrong note, or present an author's idea from a literature note as your own conclusion.
What to do: require file paths for every claim (the prompt in the agentic search section does that), open the source before reusing anything, and check that a note exists before linking it (that's one of the rules in my AGENTS.md). qmd's contexts help here too: a hit labeled "notes on books, articles and videos: other people's ideas" is much harder to misattribute.
AI-written notes polluting your results
When agents write summaries, wikis or reports into your vault, those notes contain all the right keywords, so they rank high. In my own tests, AI-generated wiki articles showed up right next to my permanent notes. Over time, you can't tell which ideas are yours, which breaks a basic assumption of personal information management: the person who organizes the notes is the person who retrieves them.
What to do: give AI-written notes their own folders (or a property or tag that marks them), and scope searches when you want your own thinking: for a folder called "AI notes", -path:"AI notes" in Obsidian Search, rg -g '!AI notes/**' in the terminal, a separate qmd collection you can exclude from default queries. Watch the Collector's fallacy too: AI makes capturing and summarizing almost free, and every unprocessed summary lowers the precision of every future search.
Cognitive debt
The point isn't to avoid AI search. It's to stay the person who knows what's in your notes. The Sparrow finding is a warning and a hint at the same time: if you remember where things are, good structure (titles, MoCs, note types) keeps you oriented even when an AI does the retrieving.
What to do: let AI propose, and do the last step yourself. Open the notes it surfaces, read them, link the ones that matter, and write the conclusion in your own words. When an AI answer surprises you, treat it as a cue to revisit the source notes, not as the answer.
FAQ
Can Obsidian search by meaning? Not on its own. Semantic search needs a plugin (Smart Connections, Similarity, Seek, Copilot with Miyo) or an external tool like qmd. Hybrid search (keyword + semantic) works best.
Is semantic search private? It depends on where the embedding model runs. Smart Connections and Similarity use local models by default, and qmd runs entirely on your machine. Plugins configured with a cloud embedding API send your note text to that provider. Either way, treat the index files (.smart-env/, qmd's index.sqlite) as sensitively as your notes: research has shown that short texts can be recovered from their embeddings.
Conclusion
AI search works on top of your notes: the better your titles, aliases, properties and links, the better it finds them, and the easier it is to check what it found. Keyword search gives you certainty, semantic search gives you meaning, hybrid search with a reranker gives you both, and agents add the loop of searching, reading and refining. Whatever you pick, run your 20 queries before you trust it. The next part shows how I set all of this up.
Next in the series: Set Up AI Search for Your Obsidian Vault - qmd, MCP Servers and AI Assistants. Previous: The Best Obsidian Plugins for Finding Notes.
Prefer to read the whole series in one place? I turned it into an ebook, The Obsidian Search Handbook, with an exercise at the end of every chapter (the Complete edition adds a starter pack and worksheets).
Free cheat sheet. The commands and operators worth remembering, and the search escalation ladder (which tool to try first, depending on what you remember about the note), on 13 pages you can keep next to your vault. Enter your email and I'll send it right away: the Obsidian Search Cheat Sheet.
 Sebastien Dubois
Get the free Obsidian Search Cheat Sheet. 13 pages to keep next to your vault: the search operators worth remembering and the search escalation ladder. Enter your email and I'll send it right away. You'll also get a few short follow-up emails about finding notes in Obsidian, and you can unsubscribe at any time.
About Sébastien
Ready to get to the next level?
Found this valuable? Share it with someone who needs it.